Reverts #726 which added an early optimization to the SSAify pass in skipping
over phi creation if only one unique operand. This is no longer necessary with
the addition of a phi elimination pass added in #739.
This is an alternate take on phi elimination to the one we pursued over VC w
@poteto driving. This version exploits the RPO ordering of blocks to do phi
elimination in a single pass when there are no loops, and to minimize repeated
visits when there are loops. The main difference is when redundant phis are
removed. Rather than eagerly walking through the CFG for each pruned phi to
rewrite its uses, we build up a mapping of rewritten identifiers. As we walk
through subsequent instructions, we rewrite each place based on that mapping. We
continue cycling through the blocks so long as a given iteration *both* added
new rewrites (meaning there may be subsequent uses to rewrite) *and* there are
back-edges. With no loops this results in a single visit of each block and of
each instruction, but even with loops this is bounded.
This diff adds styling to the compiler options editor. The floating input/output
toggle button on small screens now spans the bottom of the screen, so that it
doesn't block the compiler options.

Height overflows when adjusting screen size are complicated by Monaco Editor and
will be addressed in a later diff.

Test plan:

Start Playground and see the latest look of the compiler options editor beneath
the output section.
Removes all the `path: NodePath` values from various IR node types, replacing
them with `loc: SourceLocation`. This type is an alias for babel's source
location type plus a "generated" variant. The "OtherStatement" kind also used
the `path` to print back the original AST (since we don't look into these);
instead, we now capture the underlying `node` and emit that as-is during
codegen.

While I was doing this, i also fixed up the places where we had passed a null
path; the vast majority have a clear place we can pull a location from. For
example, `a ?? b` syntax creates some places/instructions for the `a != null`,
but those can all point back to the `a` location.
This commit introduces a small update to our fixture tests to allow certain jest
`test` modifiers to be added to fixture tests via a leading prefix in the
fixture name.

For example, `only.my-fixture.js` is the equivalent of writing
`test.only("my-fixture")`.
This currently basically lowers the code into the equivalent of

```

const vLeft = <left>;

const vNull = null;

const vCond = vLeft != vNull;

vCond ? vLeft : <right>

```

I created a temporary `Place` to hold the `null` constant value because the
binary operator in HIR accepts only `Place`s. Not sure if this is the preferred
approach. Alternatives I could think of:

-  Allow constants as an alternative to Place?

- A `NotNull` operator for `<x> != null`

- Some other extension to the HIR?
## Proper Detection of Out-of-order Functions

The no-use-before-define rule from ESLint has a strange behavior in which it
treats variables differently than functions:

```javascript

function foo() {

return bar(X);

}

const X = null;

function bar(x) {}

```

By default, `bar(x)` has two errors: one because X is used before defined, and
once because `bar` is used before defined. The rule has an option `{variables:
false}` which only enables validation when the variable is from the same "scope"
as the reference, the net result of which is it means it doesn't report spurious
errors such as X being undefined. There is _also_ a `{functions: false}` option,
but for some reason that doesn't work the same way, it just turns off all
validation of references that came from functions. So enabling that option would
suppress the (spurious) error on invoking `bar()` above, but causes the rule to
miss invalid code such as:

```

function foo() {

return bar();

function bar() {}

}

```

This PR adds a fork of the rule that makes `{functions: false}` behave similarly
to `{variables: false}`, which should help avoid some of the spurious errors i
saw internally. The rule is exported from Forget itself, which will make it
easier to consume internally, in tests, and in the playground.

## Targeting the validation to Forget functions

Even with the above, there are still some false positives coming from code such
as:

```javascript

const x = foo();

function foo() {}

```

This PR changes codegen to ensure that the output of a function _always_ has the
body starting with 'use forget'. The ESLint rule then only looks at function
declarations/expressions whose body starts with that expression. The new unit
test confirms that the validation finds invalid reorderings even on functions
that weren't explicitly tagged as 'use forget'.
This just piggybacks on the infrastructure for handling Env.#variables.

In the future, a better approach would be to simplify the environment creation
and merging by leveraging the SSA property of the new IR -- 1) We don't need to
track IdentifierId per environment as they are all    unique 2) Rather than
tracking values, we can just track Identifiers because    Identifiers can never
be reassigned.
The semantics of lvalue changes based on whether lvalue.place.memberPath is null
or not. If it's null, then lvalue.place acts as the lvalue for the instruction,
otherwise it's just a reference to the memberPath specified location.

Ideally we'd have an MemberExpression IR that lowers this complex lvalue into a
temporary Place, uses this temporary place and stores back to the
MemberExpression.

Working around for now, will refactor to create a MemberExpression in the future
if necessary for other analysis.
Instead of using Place, use Identifier as the unit of comparison in SSA.

Place is too high level and can not be substituted for other Places (even those
with the same Identifier) as Place contain higher level metadata such as
memberPath.
Currently, HIR doesn't load global idenfifiers into a temporary Place which
means our SSA transform breaks when it tries to lookup this global identifier.

Instead of throwing, let's log and return the old place. This works for now but
will probably break when we start mutating globals, but at that point our HIR
builder will need fixes.
ESLint's default parser doesn't support any non-standard syntax, which includes
JSX. So when I added the ESLint validation step to the playground, it meant that
valid examples containing JSX still reported "invalid output". I tried to use an
alternative parser, but I couldn't figure out the right webpack incantations to
make `@babel/eslint-parser` or `hermes-eslint` work. I even tried recreating
some of their code to avoid problematic imports, no dice.

Instead this PR:

* No longer uses the `postCodegenValidator` step, and runs the validation on the
output after compilation completes. This is better anyway since we can see the
output *and* the error messages

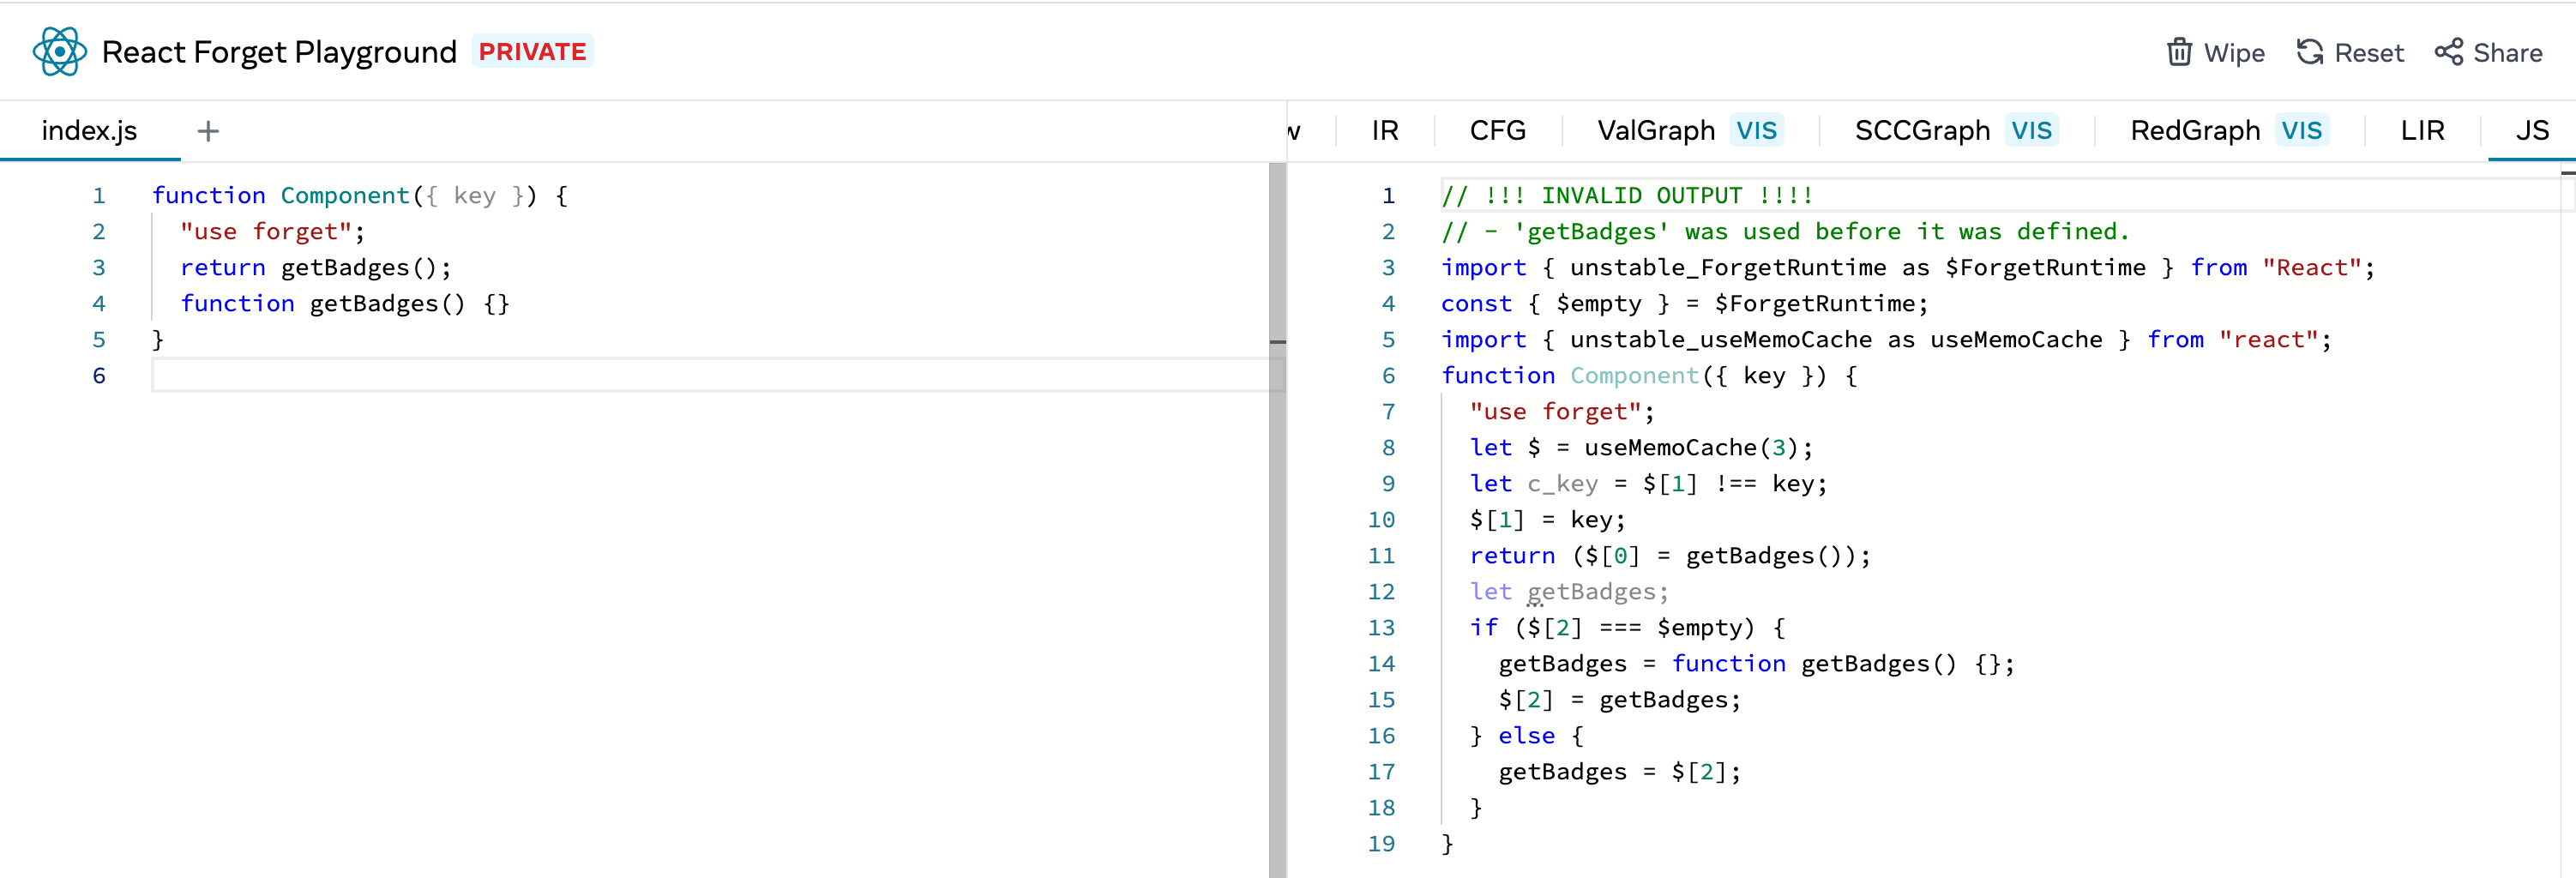
* Shows rule violations as an "Invalid output" comment

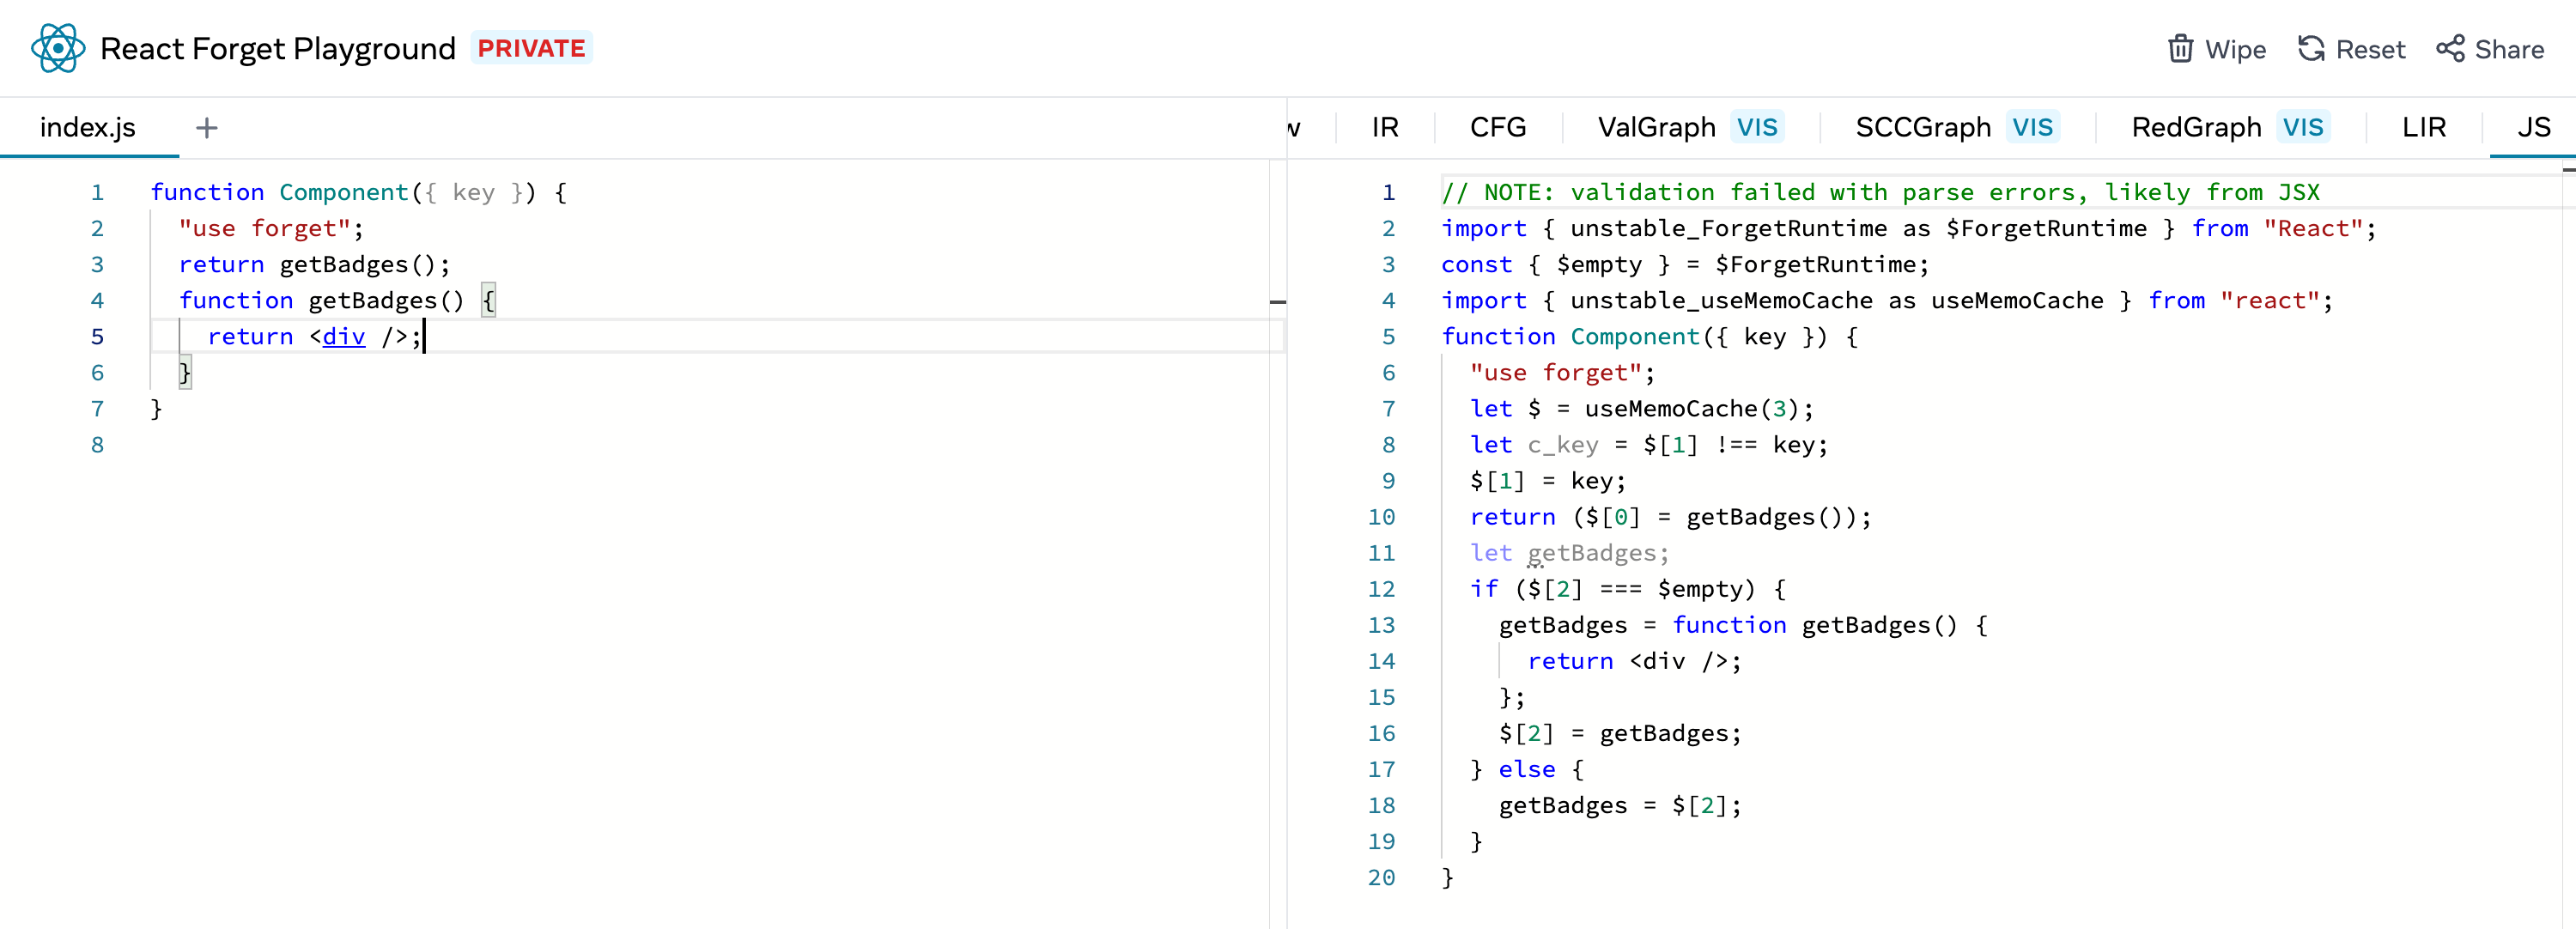
* Shows parser errors as a note (mostly to indicate that the validation step
couldn't run, there could still be no-use-before-define violations that weren't
found)

Invalid example:

<img width="1502" alt="Screen Shot 2022-10-21 at 9 50 23 AM"
src="https://user-images.githubusercontent.com/6425824/197249007-1ec244a0-6dfe-4ec6-a0d0-60302efd86bd.png">

Sample example but with some JSX:

<img width="1500" alt="Screen Shot 2022-10-21 at 9 50 39 AM"
src="https://user-images.githubusercontent.com/6425824/197249030-e68ba968-4101-47c7-a148-f548f84f375c.png">
Imports the runtime from `React.unstable_ForgetRuntime` rather than from a
separate module. The hope is that any code that gets transformed already has a
dependency on React anyway, so we can avoid adding a new dependency that other
systems don't know about.

While here, i also cleaned up the `guardThrows` flag (we still parse it if
present and warn, rather than throwing, to make it easier to adopt the latest
version in various places).
#686 added an option to validate generated code after transformation and adds an
ESLint-based validator function to transform-test. Unfortunately it isn't super
easy to wire up ESLint for use in a browser: traditionally the ESLint project
specifically did _not_ support browser builds, but they recently have relaxed
this because they added a browser playground on their website. There isn't
official support, but the [playground
repo](https://github.com/eslint/playground/blob/f3b1f78cc1c06dadfe7bb50c6c0f913c0d23670d/webpack.config.js)
has a webpack config that, when combined with requiring a specific file, allows
making things work in a browser.

I tried using this directly in our playground app but Next's default webpack
config doesn't work. So I created a separate package, playground-validator,
which exports a webpack-built version of `eslint.Linter`. Then the playground
can consume that, and everything works:

## Test Plan 👀

Confirmed that a known problematic example displays the validation message in
playground (both locally and on the preview deployment):

<img width="1500" alt="Screen Shot 2022-10-20 at 12 22 59 PM"
src="https://user-images.githubusercontent.com/6425824/197041265-966ffda2-a3d0-450e-8fc4-fd1a7ca06e1a.png">
Adds a new compiler option `validateNoUseBeforeDefine`, which enables a
post-codegen pass to validate that there are no usages of values before they are
defined (which causes a ReferenceError at runtime). This can occur when a value
is accessed when its in the TDZ (temporary dead zone), after the hoisted
_declaration_ but before the variable is defined:

```javascript

function foo() {

x; // x is in the TDX here: the binding from the subsequent statement is
hoisted, but x is not yet defined.

let x;

}

```

* The validation is off by default, but enabled in transform-test

* The validation crashes compilation, rather than bailout, because the code has
already been mangled and we can't roll back at the point the validation runs.

* The validator uses ESLint's no-use-before-define rule by printing the program
to source and then configuring ESLint to use Hermes parser.

* transform-test now supports tests prefixed with "error." to indicate tests for
which compilation is expected to crash (not just bailout), and the expect file
includes the error message.
 Jan Kassens
 Sathya Gunasekaran
 Lauren Tan
 Joseph Savona
 Robert Zhang